Many companies detect problems only after they have already had an impact: an order is delayed, a cost spikes, a metric drops, a customer complains, or a process stops working properly.
In many cases, the warning signs were already there. The problem is that they were hidden among thousands of data points, emails, transactions, tickets, or system logs. AI for anomaly detection makes it possible to identify unusual behaviour before it turns into a serious incident.
What is an operational anomaly?
An operational anomaly is any behaviour that deviates from what is expected within a process. It may be an unusual increase in tickets, a sudden drop in sales conversion, an order with atypical characteristics, recurring delays at a specific stage of a process, abnormal resource consumption, or an unexpected cost deviation.
It does not always mean that there is an error. Sometimes it may be explained by a campaign, a change in demand, or a temporary situation. But it does indicate that something deserves attention. For management, the difference between detecting an anomaly early and dealing with an uncontrolled incident can be significant.
Why do many companies detect problems too late?
Teams often rely on periodic reports, dashboards, or manual reviews. These tools are useful, but they have one limitation: they often reveal the problem after it has already happened. Anomalies can also be difficult to spot at a glance. An isolated data point may look normal, but when compared with its history, other processes, or similar patterns, it may reveal a deviation.
For example, an 8% increase in incidents may not attract attention. But if it occurs in a specific category, in a particular region, and after an operational change, it may be a critical signal. AI helps identify these relationships without relying solely on manual reviews.
How can AI help?
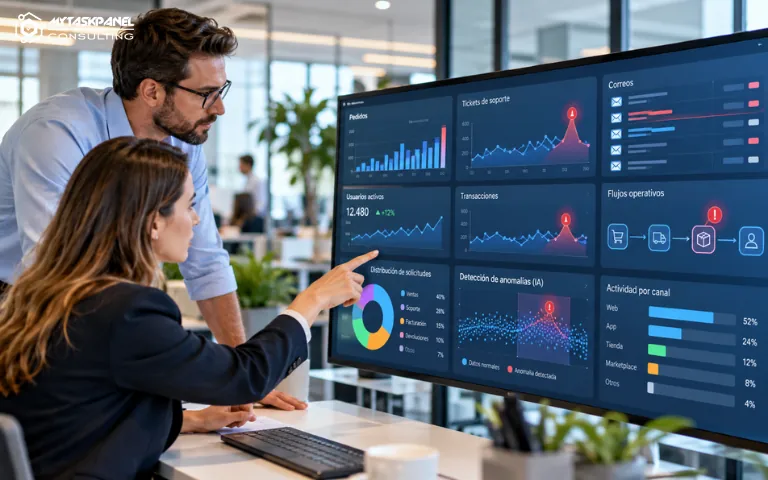
Artificial intelligence can analyse large volumes of data and detect patterns that deviate from normal behaviour.
This can be applied to sales processes, internal operations, customer service, production, logistics, finance, or technology systems.
AI can detect, for example:
- Orders with unusual amounts or conditions.
- Repeated delays at a specific stage.
- Abnormal increases in tickets or complaints.
- Unexpected changes in sales conversion.
- Cost deviations compared with forecasts.
- Unusual technology consumption.
- Recurring errors in billing or documentation.
- Changes in customer or user behaviour.
The value lies not only in detecting the anomaly, but also in generating an alert that is understandable and actionable
Use cases for management
- In operations, AI can identify delays before they affect the customer. If certain orders start taking longer than usual, the system can issue an alert before complaints begin to accumulate.
- In finance, it can detect expenses, payments, or invoices that fall outside normal patterns. This helps teams review potential errors, duplicates, or budget deviations.
- In sales, it can flag drops in conversion by channel, team, region, or customer type. Instead of discovering the issue at the end of the month, management can act sooner.
- In customer service, it can identify an unusual increase in enquiries about a product, service, or incident. This makes it possible to anticipate responses, reinforce teams, or address the root cause.
- In technology, it can detect increases in errors, response times, or infrastructure consumption.
What data does the company need?
AI cannot detect relevant anomalies if the data is incomplete or too fragmented. Before applying this technology, it is important to review what information is available, which systems contain it, how frequently it is updated, and what level of quality it has.
It is also important to define what “normal” means for each process. There may be seasonality, campaigns, production cycles, sales peaks, or differences between markets. The solution must take this context into account to avoid irrelevant alerts.
Useful alerts, not noise
One of the risks of these systems is generating too many alerts. If everything appears urgent, then nothing really is.
That is why anomaly detection should be combined with priority rules, impact thresholds, and business context.
Some deviations only require monitoring, while others should be escalated immediately to the relevant person. A good solution should explain what has been detected, why it matters, and what action could be taken.
The role of human review
Detecting an anomaly does not mean automating the final decision. In many processes, AI should act as an early warning system. It identifies signals, prioritises issues, and supports investigation, while the final decision remains with the responsible team.
This is particularly important in sensitive processes such as payments, contracts, strategic customers, regulatory compliance, or decisions that affect service delivery.
The most useful combination is often AI for detection and people for interpretation and action.
How can the impact be measured?
The impact of an AI anomaly detection solution can be measured using specific indicators:
- Reduction in incidents detected too late.
- Average response time to deviations.
- Number of useful alerts compared with irrelevant alerts.
- Costs avoided due to errors or delays.
- Improved deadline compliance.
- Reduction in complaints.
- Greater operational stability.
The key is to link detection to business outcomes, not just technical accuracy.
AI for anomaly detection makes it possible to move from reactive management to a more proactive approach to monitoring processes, data, and operations.
At MyTaskPanel Consulting, we design AI solutions connected to each company’s real systems, combining data, automation, and human oversight. Does your company detect problems only after they have already affected the business? Contact us and we will assess how AI can be used to anticipate operational risks.


